

Don’t trust me, these headlines speak for itself-
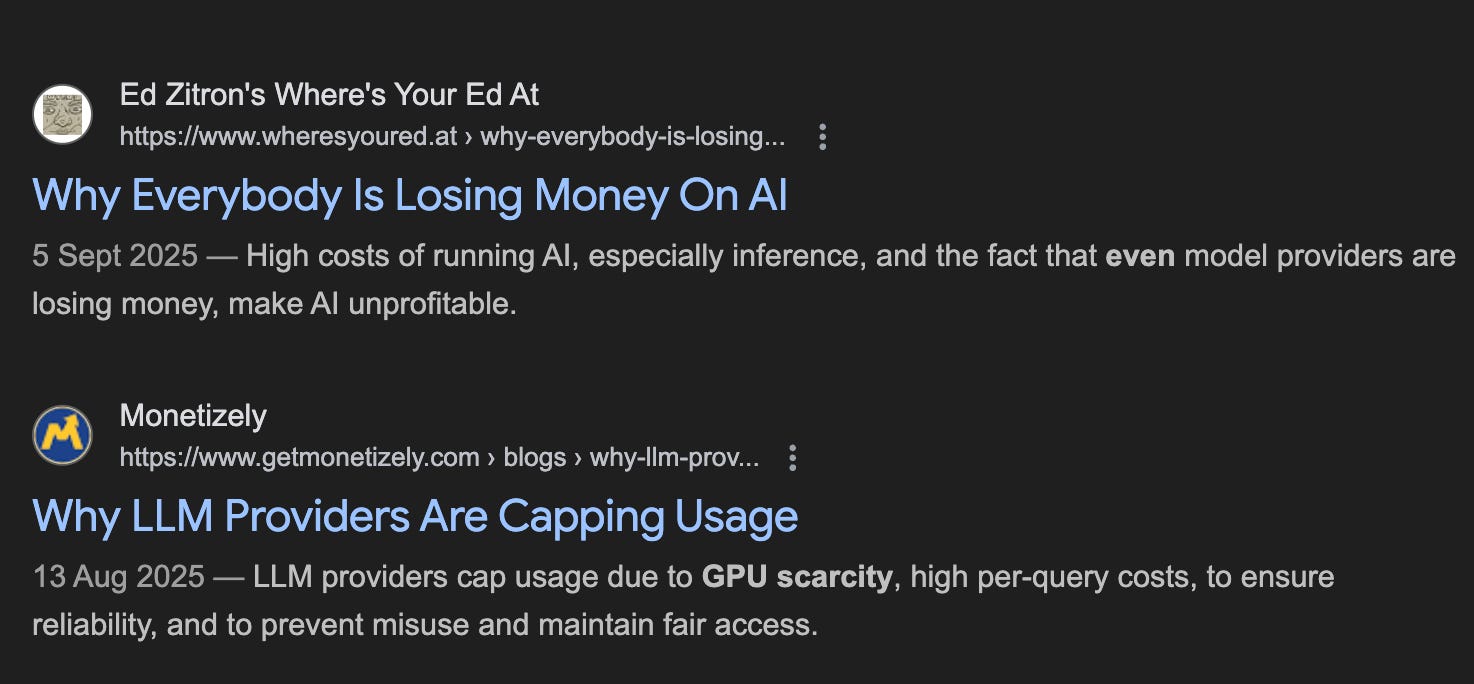
Take a look at these screenshots. Infact, if you are a Cursor user or using any AI tool out there, you must have noticed this first hand -
Almost everyone is capping their model usage because GPUs are not being fully utilized.
The result? Massive AI compute spend, much of it wasted. In short, people are losing money on AI infrastructure, and only the organizations that can optimize their GPU pipelines will survive in the current landscape.
It’s also worth acknowledging the hype: we are in a bubble of AI investment. Companies are buying hardware and scaling models, but without GPU-level optimization, that investment doesn’t translate into proportional throughput or revenue. We need to understand why pipelines plateau, which bottlenecks exist, and where we can intervene to actually get performance gains. Here’s another

And it’s not just small startups.
In 2024, Microsoft researchers published a paper “An Empirical Study on Low GPU Utilization of Deep Learning Jobs” in which they profiled 400 real deep learning jobs running on their internal GPU clusters. Guess what they discovered - average GPU utilization? Just a little over 50%.
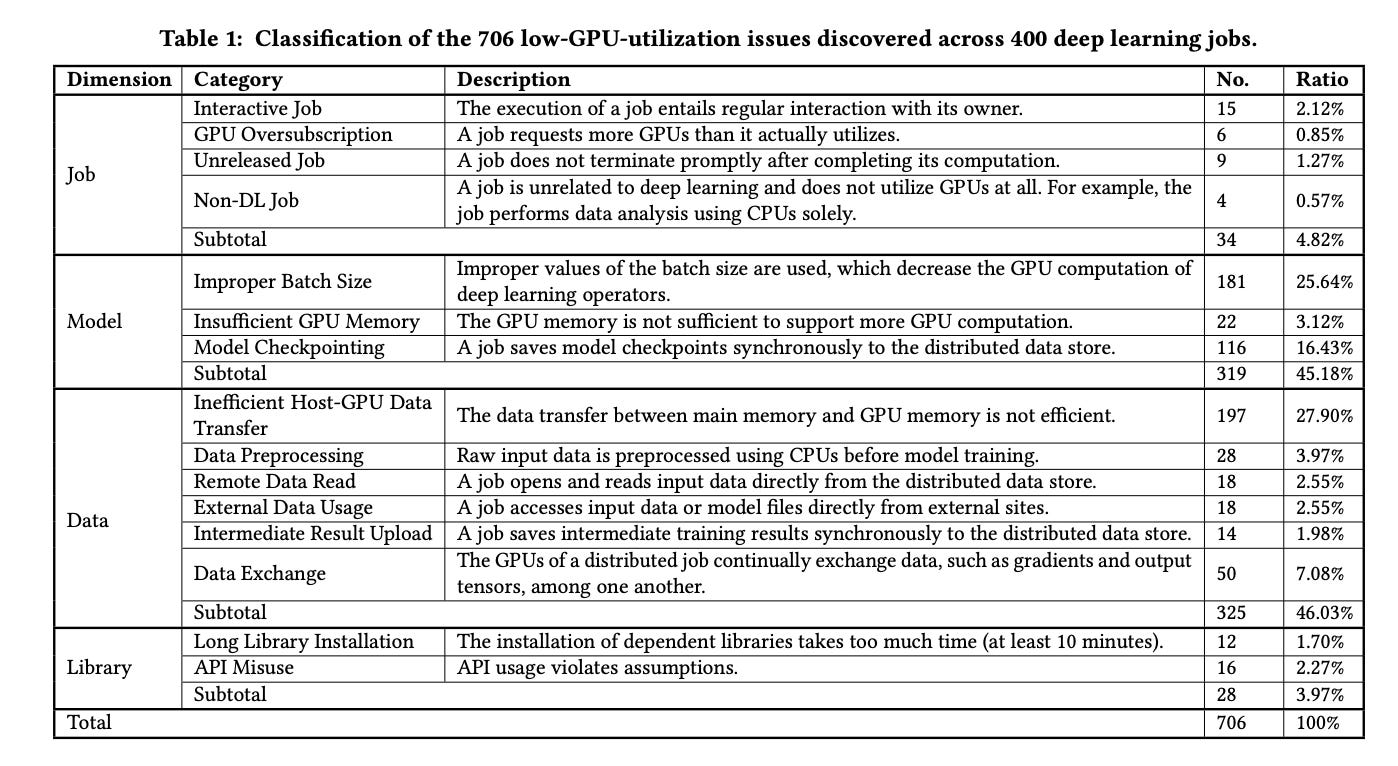
Pay attention to this stat because Microsoft is the the company providing compute for OpenAI and the mammoth that has owned a huge chunk of cloud computing market (via Azure) for years.
They are not some novices that jumped into the game yesterday. Let that sink in.
At this point, it won’t be wrong to hypothesize - Half the world’s most advanced chips sit idle.
Not because the models were bad or the hardware was slow, but because the workloads weren’t structured to use the GPUs properly. And that’s not a Microsoft problem. That’s our problem. That’s the GPU Engineering problem.
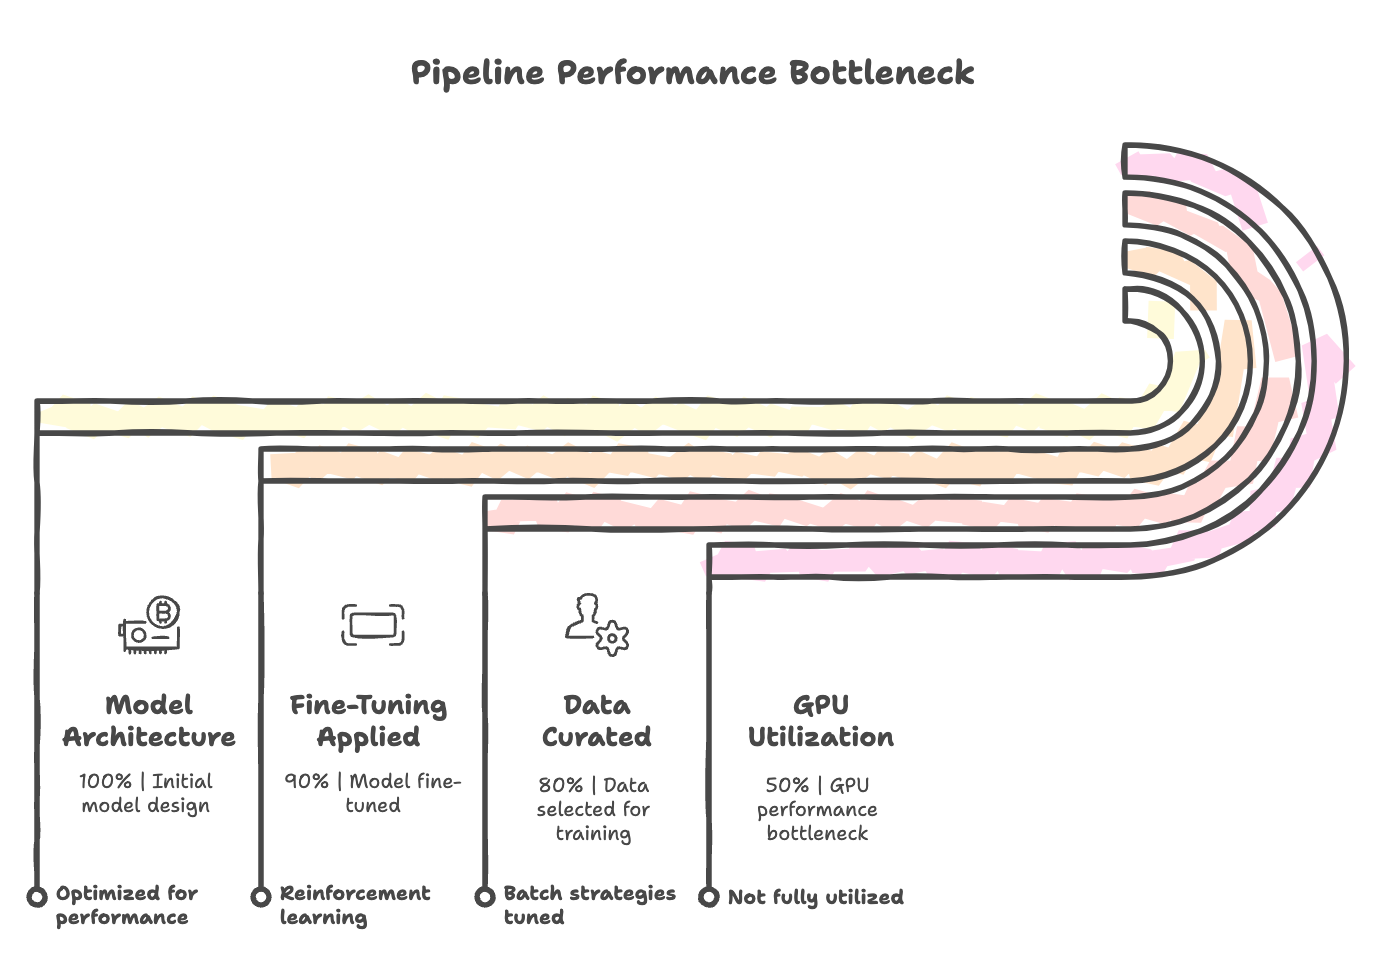
We’ve spent years perfecting model architectures, reinforcement learning pipelines, fine-tuning routines, and data preprocessing systems - the LLMOps side of things. But when it comes to hardware and actually making the GPUs listen, aka GPU Engineering, most teams are flying blind.
The GPU Ceiling Problem
Every AI team eventually hits it. You scale your model, add more GPUs, and expect the speedup curve to follow. Instead, throughput plateaus. Latency sometimes even gets worse. You look at your dashboards and see expensive GPUs sitting half-idle.
Congratulations, you’ve hit the GPU ceiling!
That GPU ceiling shows up in several AI Solution Design patterns, today we will talk the major three.
1. Ghost GPUs
This is when instead of your gf, your GPUs start ghosting you.
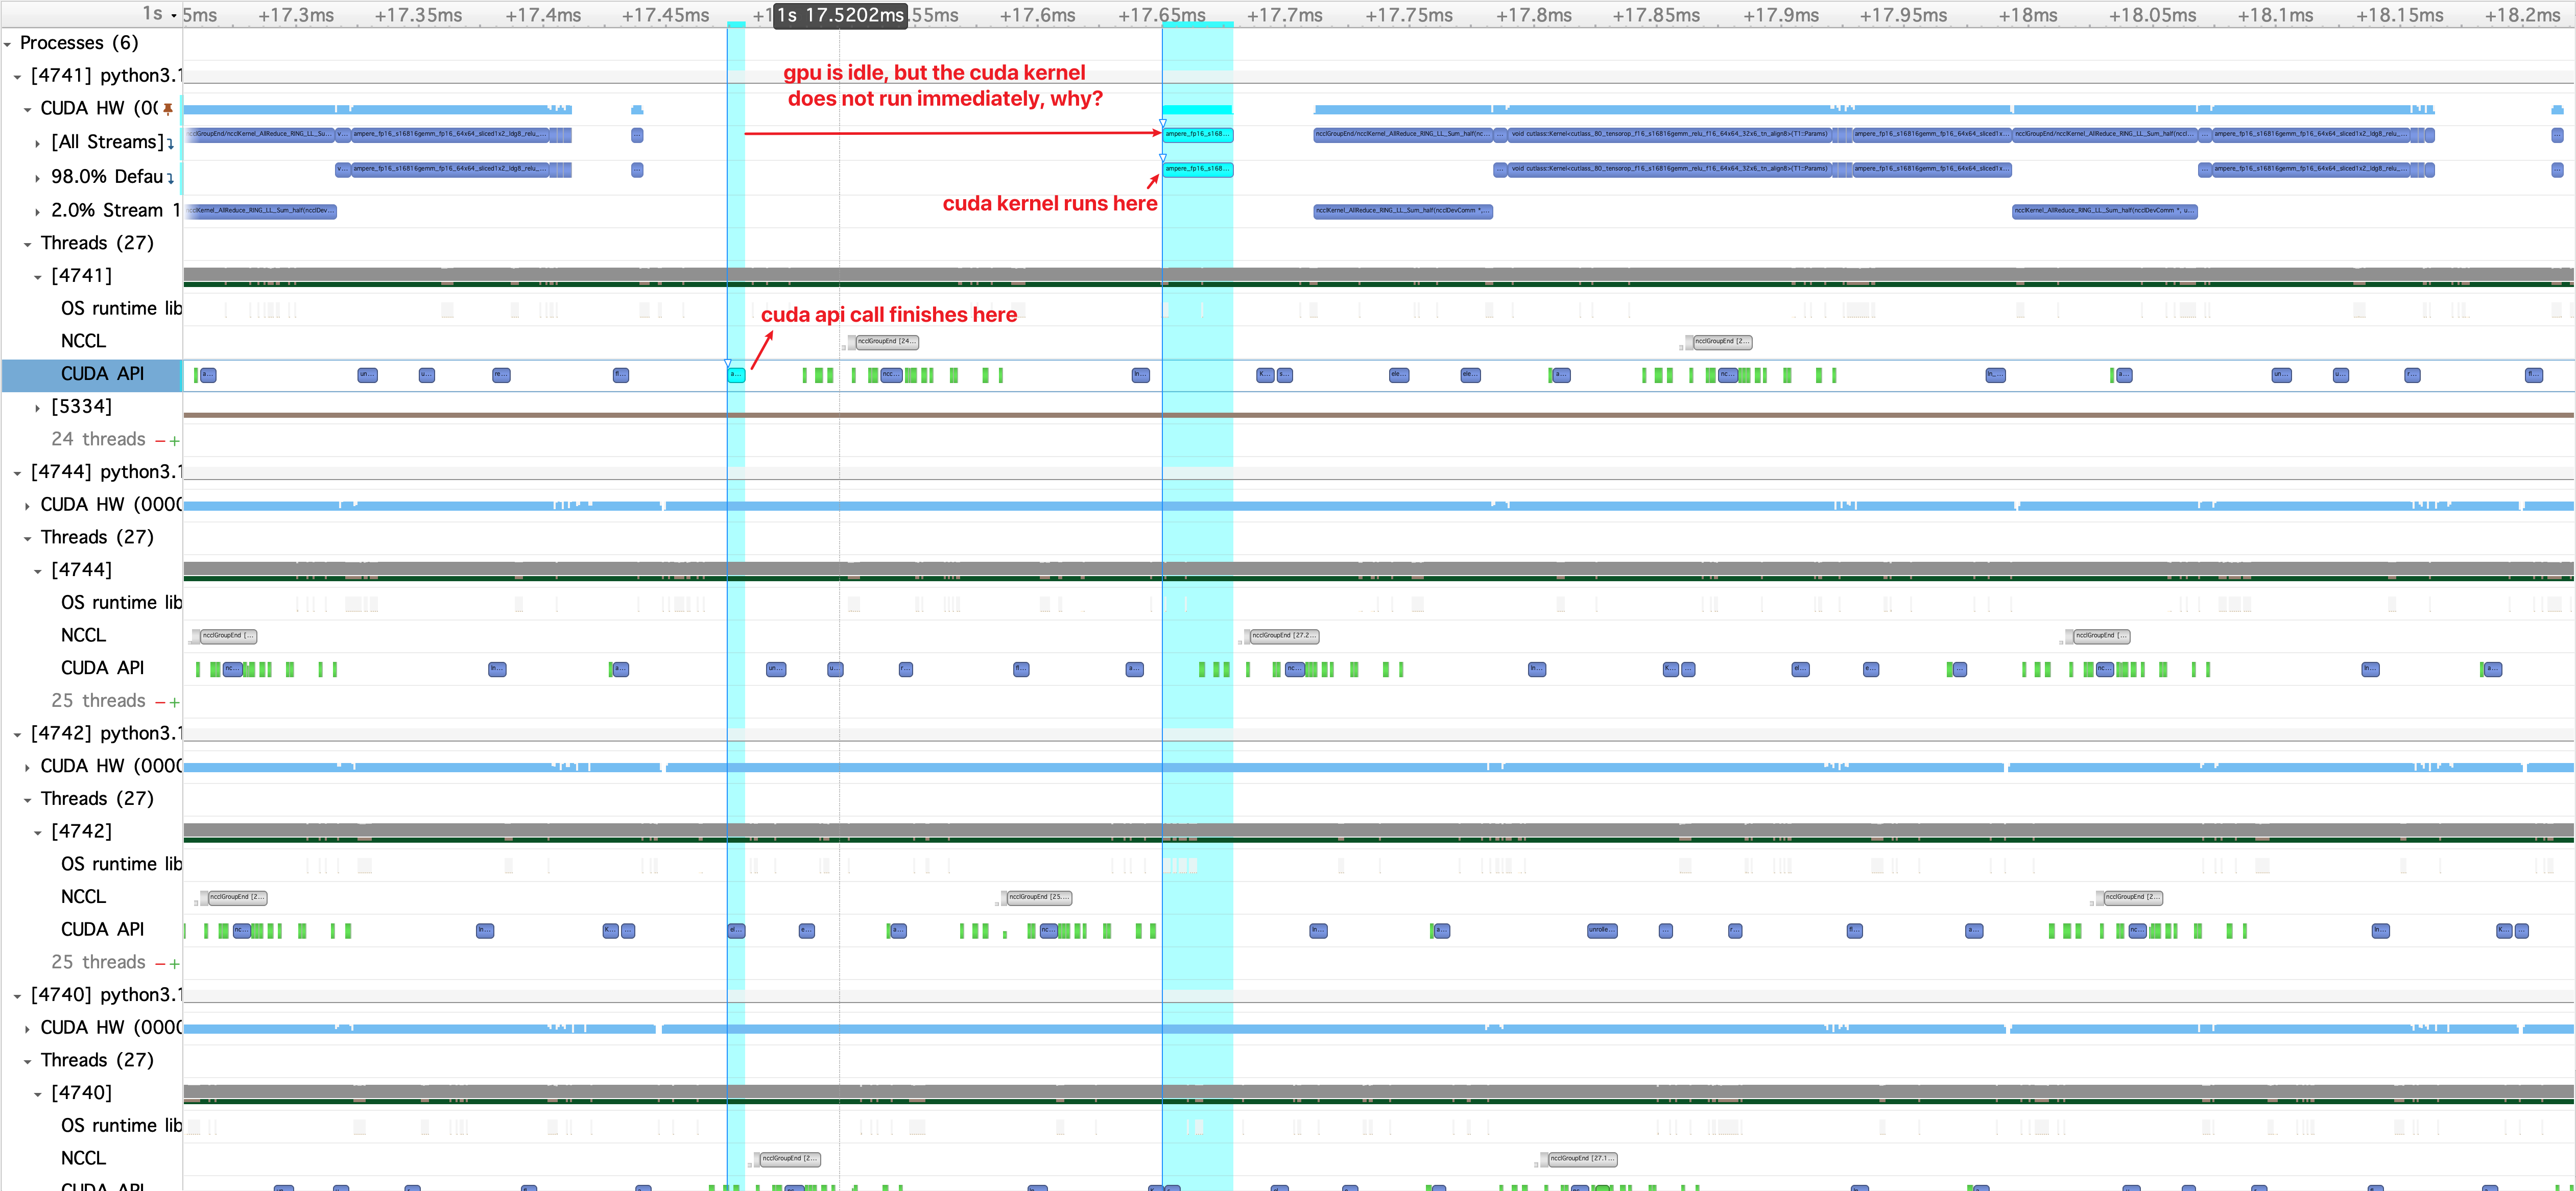
The top row shows a period (highlighted by the cyan vertical bar) where the GPU is completely blank and the annotation states: “GPU is idle, but the cuda kernel does not run immediately, why?” This pattern suggests the kernel launch was delayed, likely by an external bottleneck such as a required CUDA stream synchronization, an implicit CPU-GPU synchronization, or the need for resources (like a data transfer) that took time to become ready, causing the GPU to idle while it waits for the kernel to be scheduled.
Here’s another, see the cyan bar again-
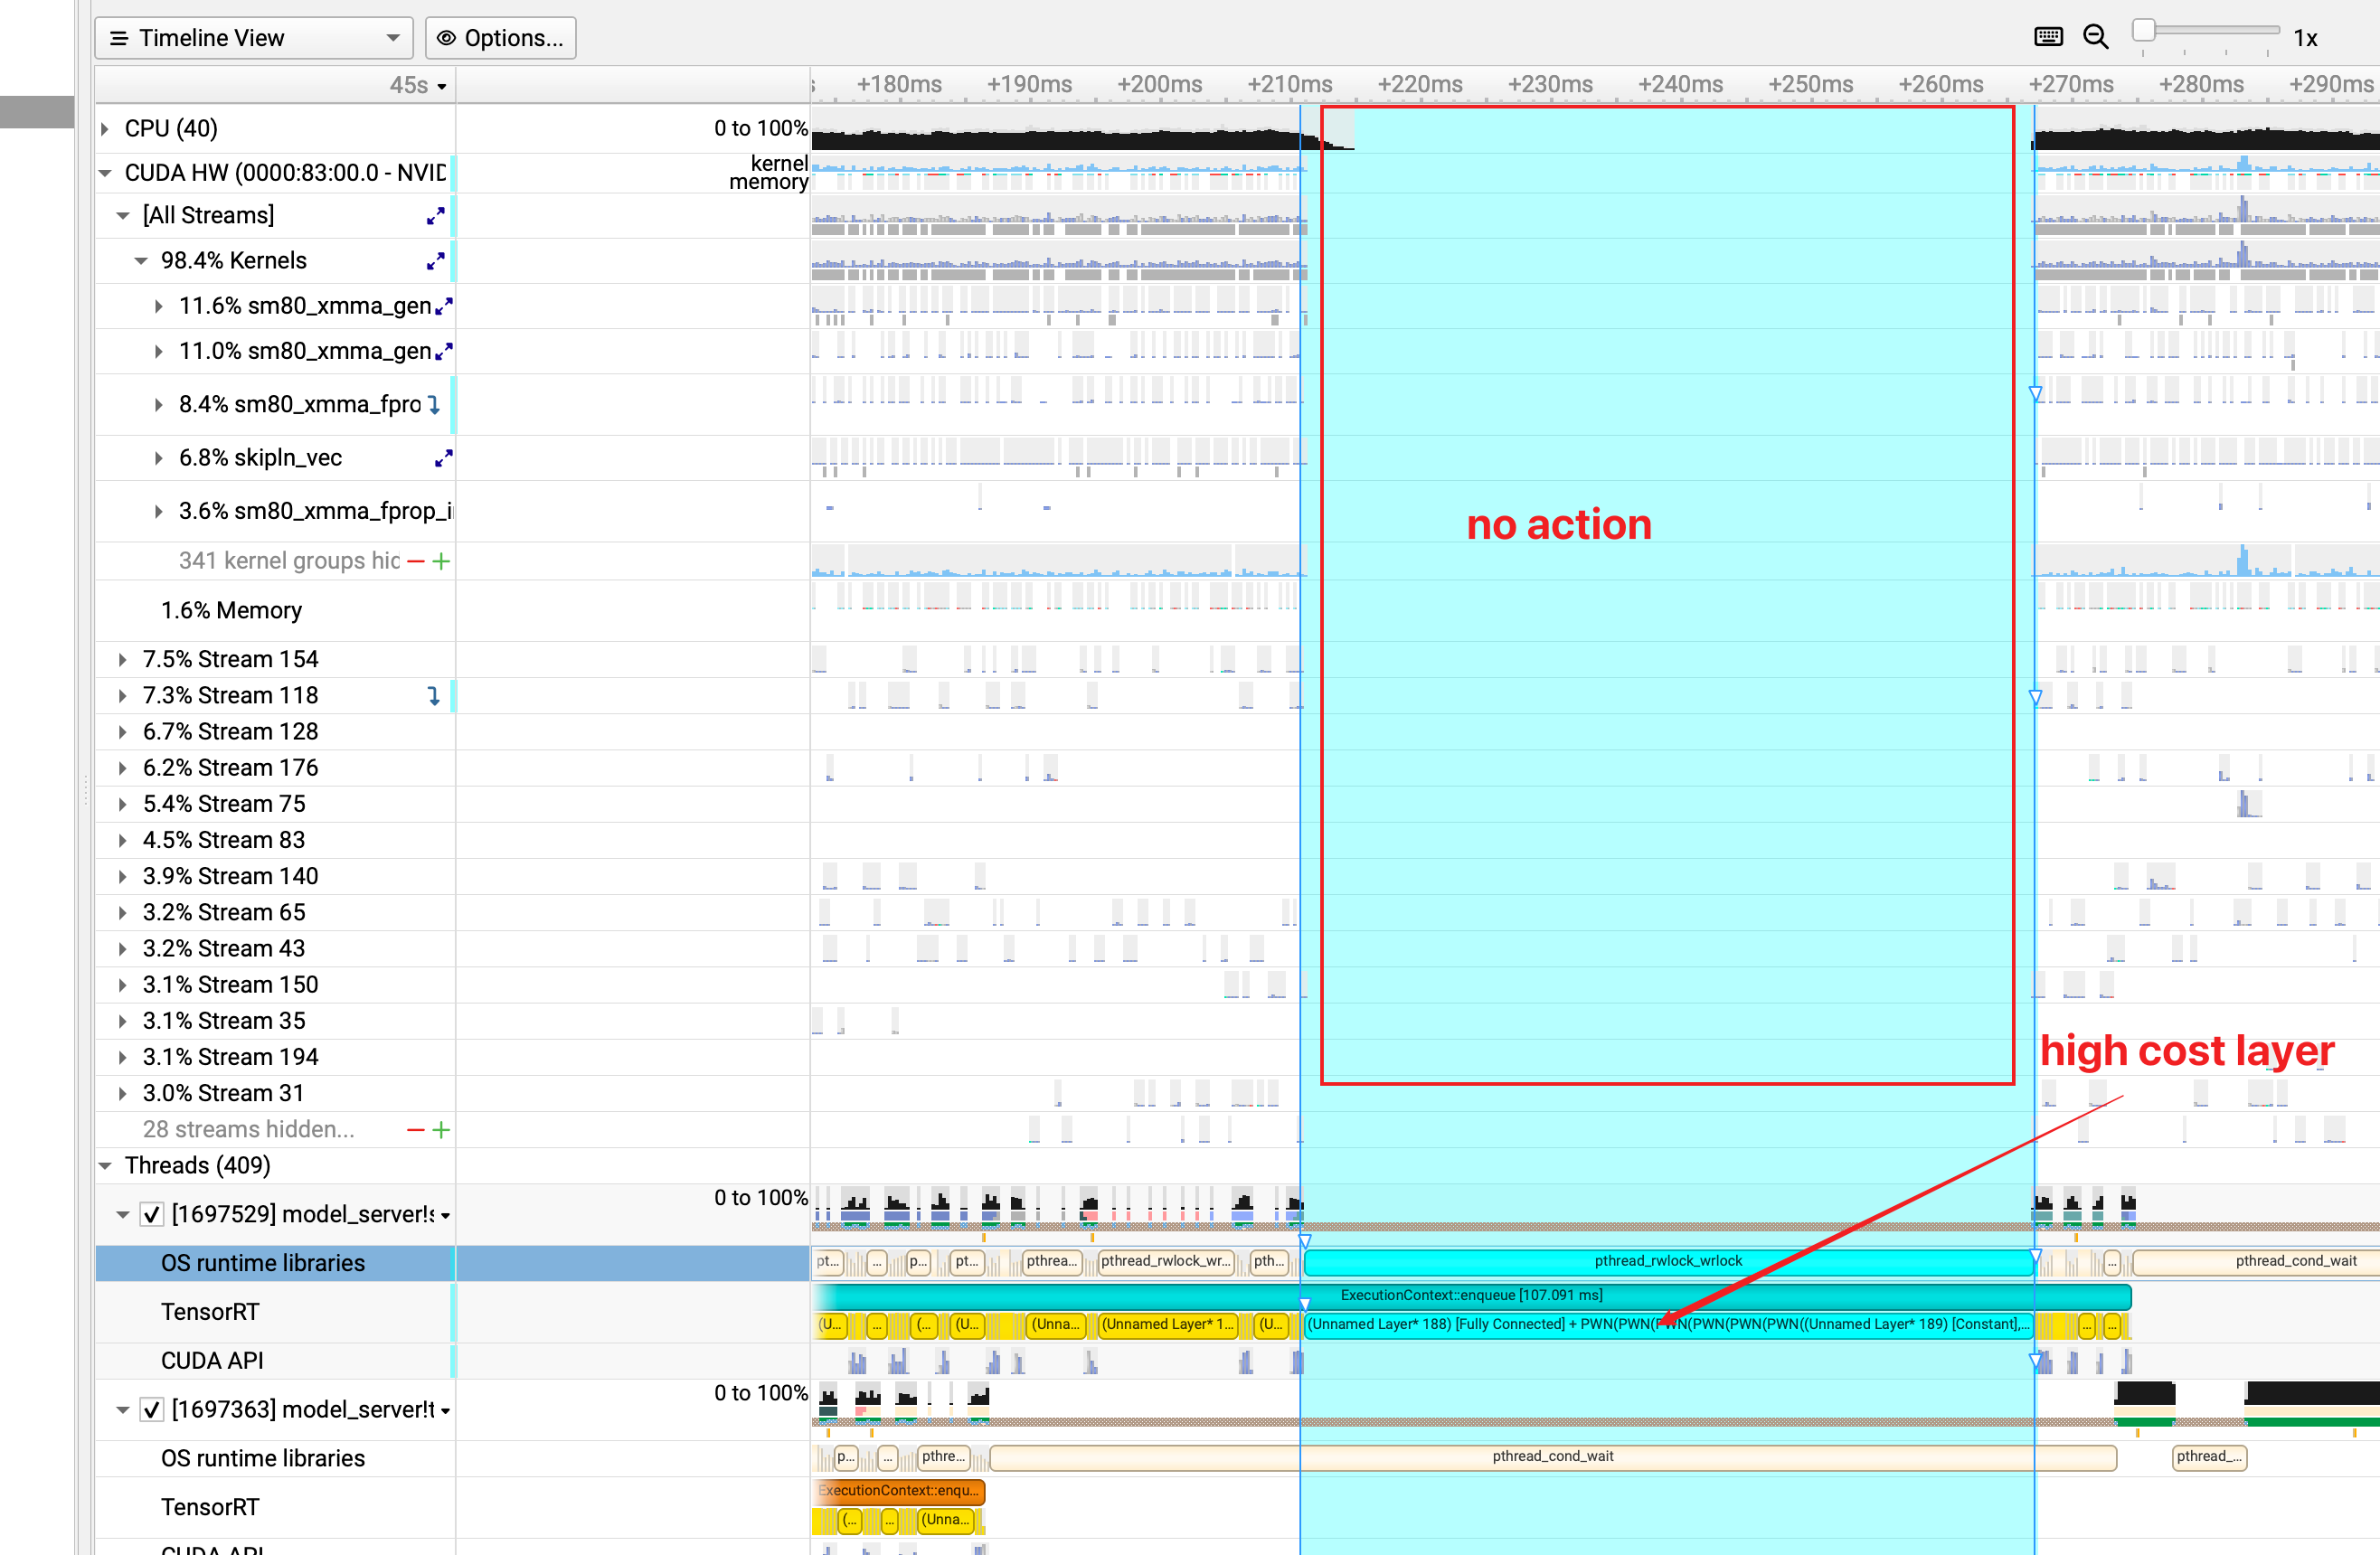
Before +220ms, the GPU is busy executing numerous small kernels. At +220ms, the last kernel finishes. The CPU threads initiate a synchronization/wait loop (_pthread_cond_wait). +220ms to +275ms, the GPU is idle (”no action”) because the CPU is blocked, unable to launch the next batch of kernels (the “high cost layer”). After +275ms, the CPU wait finally resolves, the “high cost layer” is launched, and the GPU resumes work. This is a classic and clear profile demonstrating a CPU synchronization bottleneck leading to GPU starvation/idling.
This kind of idling is the silent killer of efficiency. There can be N number of causes for idling.
the GPUs are ready, but the data pipeline starves them.
CPU–GPU transfers take too long
dataloaders can’t keep up, or
inter-GPU communication stalls the compute.
In Microsoft’s study, ~46% of underutilization issues came from this layer i.e. the data ops, not model ops. The hardware isn’t lazy, it’s just waiting.
The fix isn’t more GPUs. It’s better synchronization between your data pipeline stages. GPUs don’t “think.” They just execute. And they can only execute as efficiently as your code feeds them. Now, let’s look at the second instance of GPU Ceiling.
2. Bloated Context i.e. when the memory starts saying “It’s not you, it’s me”
In another recent 2025 paper, Mind the Memory Gap, IBM researchers found that even after massively increasing batch size during large-batch inference, throughput gains plateaued.
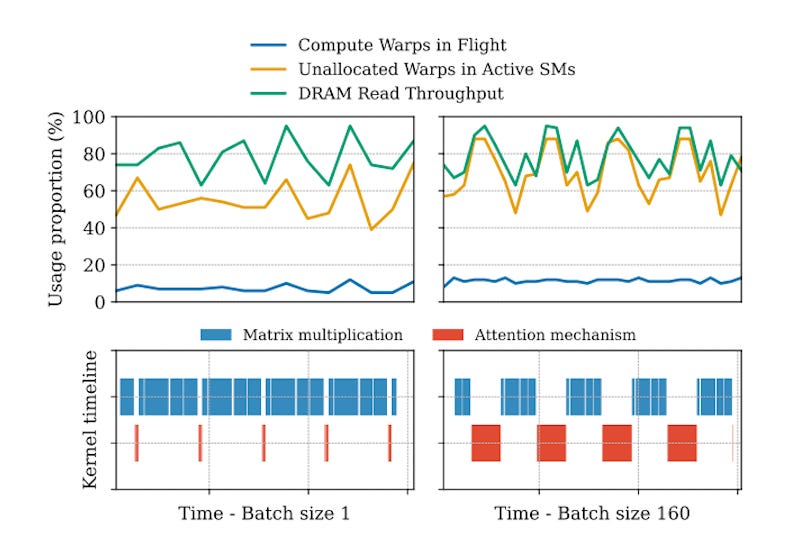
This figure shows that the Llama-2-7B decode step suffers from a performance issue best that can be called Bloated Context where the overall execution time is inflated (or “bloated”) because the GPU’s potential is wasted. The top-row metrics show that the Streaming Multiprocessors (SMs), the GPU’s core compute units were largely available but severely underutilized. Compute Warps in Flight is consistently very low (5–15%). This means the SMs are sitting idle with very few threads to execute. Unallocated Warps in Active SMs is very high (50–80%). This confirms the compute units are active but unoccupied and waiting for work. his low occupancy is an inefficiency within the kernel’s parallel execution configuration. But the DRAM Read Throughput is consistently high and maxed out (often 80–100%). This indicates the kernels are demanding data faster than the GPU’s memory subsystem can supply it. The slow rate of data delivery forces the available threads to wait for memory, leading to the observed low occupancy and rendering the workload memory-bound.
This low occupancy is an inefficiency within the kernel’s parallel execution configuration. The compute phase is “bloated” because the powerful compute units are starving for data due to the memory bandwidth limit. Fixing the memory access pattern or data reuse would be the key to shrinking this bloated execution time. Arithmetic intensity didn’t increase; DRAM stalls did.
In simple words, compute units were ready, but memory couldn’t keep up. Infact, attention kernels in decoding were stalling more than 50% of cycles waiting for DRAM reads. So, you could feed the GPU more work but it just starved faster.
This is the “Bloated Context” problem: your model isn’t compute-bound, it’s memory-bound. And memory-bound workloads behave counterintuitively i.e. scaling batch size often reduces throughput.
If you’ve ever seen your GPU metrics show “100% memory bandwidth” while your Tensor Cores sleep, that’s what’s happening. Now let’s go to the third instance of hitting GPU Ceiling.
3. Latency Mirage
This is again super-counter-intuitive because it shows a real example of when adding more GPUs can actually make you slower. Now, this one comes from Databricks, a report published by them on LLM Inference Engineering Best Practices in 2024, I think.
Databricks ran a fascinating study with Llama 2-70B inference. They scaled from 4 GPUs to 8. And the expectation was - well, the latency should drop nearly in half.
But in reality, they achieved only 0.7× improvement. Infact, it even started to regress.

Why? Communication overhead. Tensor parallelism and synchronization meant GPUs spent more time waiting on each other than computing. Model Bandwidth Utilization (MBU) actually dropped as they scaled out.
So yes, more GPUs can make you slower. Horizontal scaling without communication optimization is like trying to hold a group discussion over a laggy Zoom call.
Everyone’s talking, but no one’s actually processing. As engineers, we have built beautiful abstractions on the software side, autograd, distributed data parallelism, sharded optimizers, but we’ve lost visibility into what the hardware is actually doing. It’s left as an afterthought and we say, ok this needs Kernel Engineering, nope!!
Step 1. Teaching GPUs to Listen
Rule #1 of GPU Engineering: Profile before you optimize.
You can’t fix what you can’t see. Profiling is how you “listen” to what the GPU is telling you. It shows you where your time goes, in compute, memory, or communication and what kind of bottleneck you’re actually fighting.
If your Nsight trace shows low Tensor Core utilization but high DRAM usage, you’re memory-bound. If your SMs are idle while NCCL latency spikes, you’re communication-bound. If your Tensor Cores are maxed out and throughput scales cleanly with clock speed, you’re compute-bound.
Each case demands a different playbook.
Step 2. Responding to What the GPU Told You
Once you’ve profiled, the next step is interpretation and then, surgical optimization.
Here’s the core pattern I use: compute-bound, memory-bound, communication-bound.
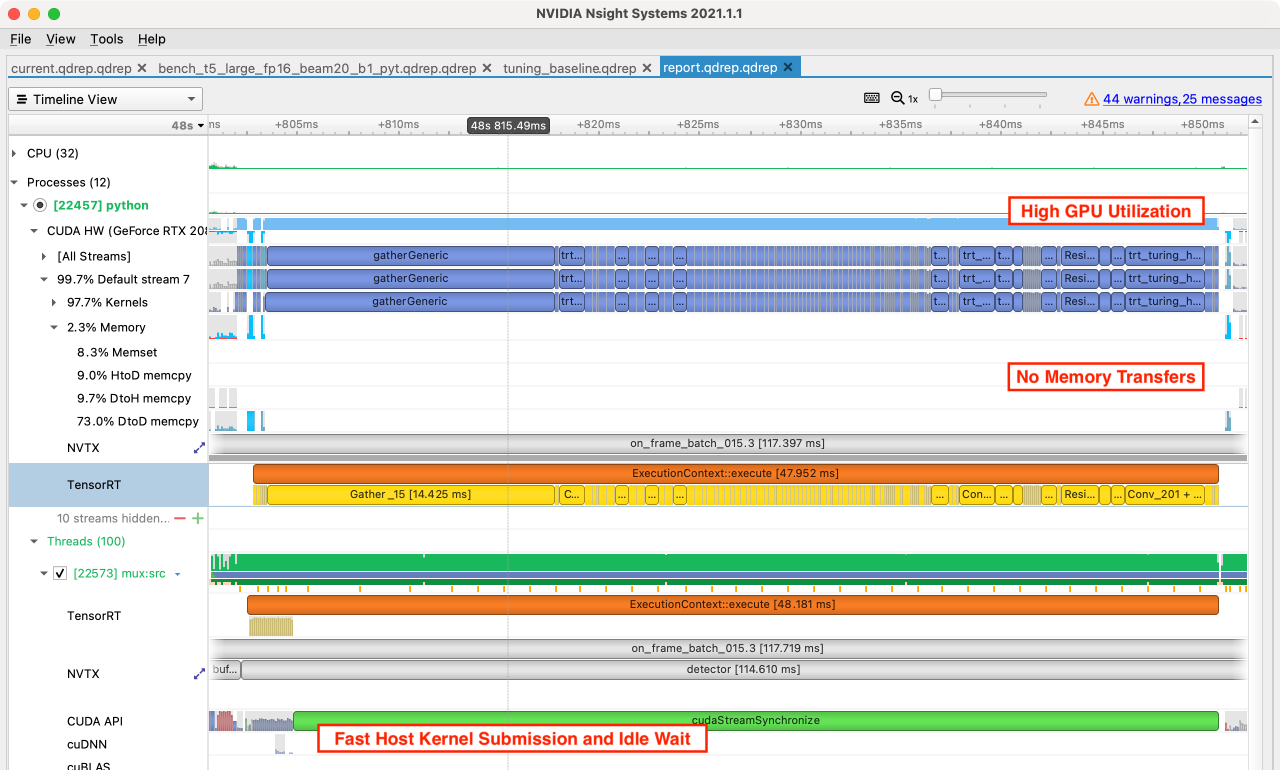
If Compute-Bound → Make Every FLOP Count
Every FLOP should do useful work. The hardware already has the horsepower so your job is to reduce the friction.
If Memory-Bound → Feed the GPU Faster
Here, compute is waiting on memory. The GPU is hungry, but the kitchen’s too slow. Structure the memory flow like an efficient data pipeline. The difference between a 40% and 90% utilization trace often comes down to whether your GPU ever has to wait for its next tensor.
If Communication-Bound → Let GPUs Talk Smarter
Multi-GPU doesn’t mean more speed, it means more coordination overhead.
Your goal is to reduce waiting time, not just add more devices. The metaphor I like: GPUs in a cluster are like team members on a factory line. If they spend all their time waiting for each other’s updates, the project stalls. Good communication design isn’t louder, it’s smarter.
Step 3. Extending LLMOps to GPU Engineering
Now zoom out. Even small inefficiencies at the GPU level don’t stay local.
They compound, especially in agentic pipelines, where tasks repeat autonomously across thousands of runs.
Each idle cycle becomes a recurring cost. Each memory stall multiplies through the system. The result: compute bills that rise exponentially with automation scale.
That’s why I say GPU engineering is financial optimization disguised as hardware tuning. You’re not just saving microseconds. Instead, you’re reclaiming dollars, power, and scalability. So treat GPUs as first-class citizens in your LLMOps stack. Monitor them like you monitor your models. Profile them with the same rigor you apply to dataset audits.
When you do that, you’ll start to notice the hardware talking back. The Nsight traces, the throughput curves, the kernel stalls, they’re all signals. The GPUs are already telling you what’s wrong. You just need to listen.
The Action Loop: Profile → Interpret → Optimize → Re-profile
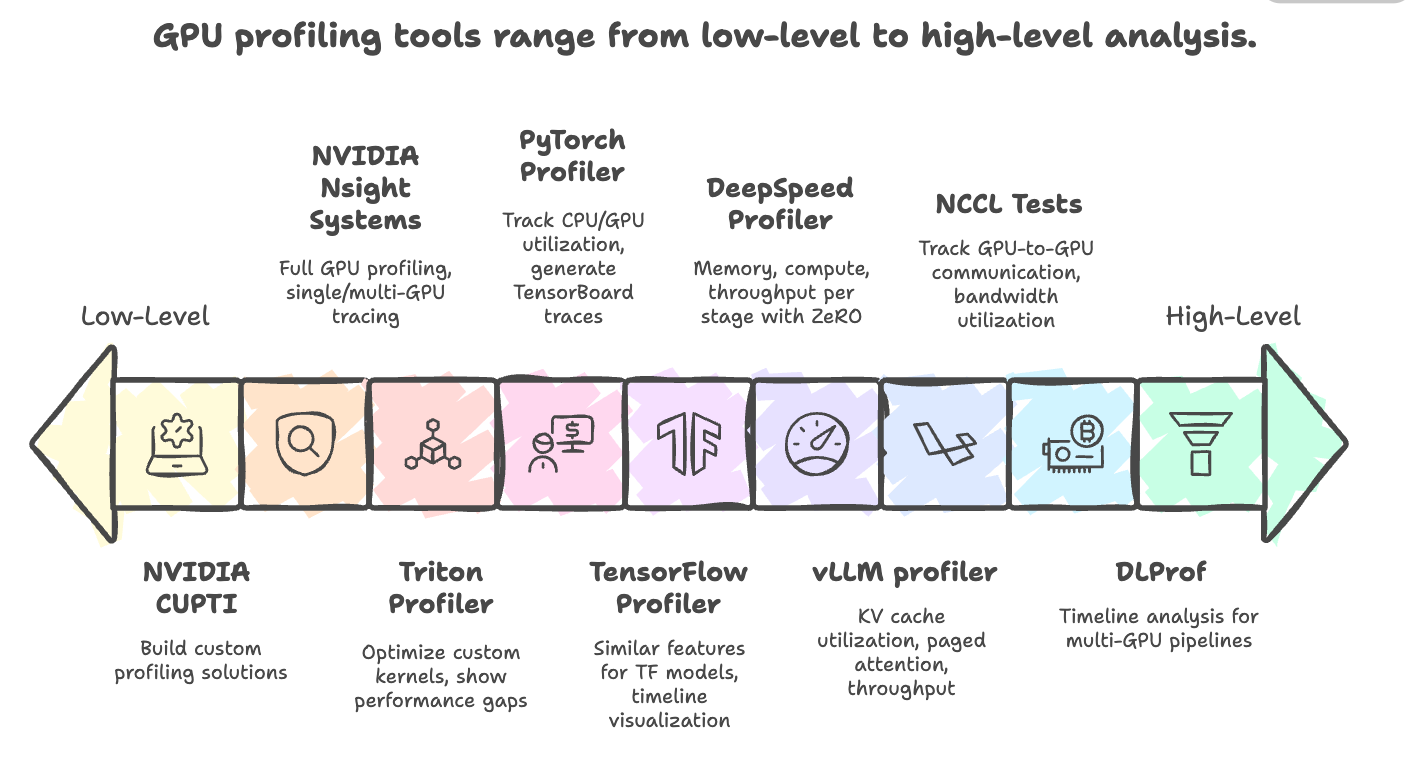
That loop is the essence of hardware-level reasoning. It’s how you turn idle silicon into productive compute.
Here’s the mindset shift I want to leave you with:
GPUs are always listening.
The question is: are we giving them clear instructions?
And in this decade of AI everywhere, that’s the difference between burning compute and building systems that last.
Thank you for coming to my TED Talk 😆
Now subscribe, share this blogpost with friends, on socials, we have a million engineers to teach!!
Great breakdown, and it matches what we’re seeing across the industry: waste isn’t usually about the tech, it’s about strategy and execution.
When companies jump into AI without clear problems, data readiness, or governance, they end up burning budgets and abandoning projects…